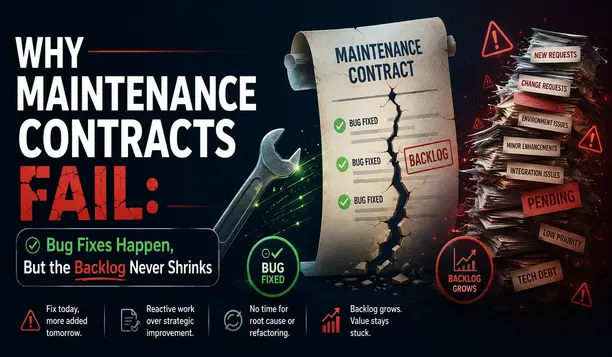

Every maintenance contract starts the same way. A vendor promises faster ticket resolution, tighter SLAs, and a backlog that finally gets under control. Six months in, the tickets are still closing on schedule. The uptime numbers look fine. The backlog, though, sits exactly where it was, or has grown. Something is wrong with a setup that can hit every SLA and still lose ground.
The problem rarely shows up in the metrics most contracts track. Ticket resolution time, SLA compliance, and uptime percentage can all look healthy while the underlying codebase quietly rots. A team can close forty tickets a month and still watch the backlog expand, because closing a ticket and fixing the problem behind it are not the same thing. Patch the symptom, log it as resolved, and move to the next ticket. Nobody asked why the same bug class keeps resurfacing in the same module for three releases later.
The metrics that hide the real problem
SLA-driven contracts optimize speed of response, not depth of fix. A ticket that gets acknowledged in fifteen minutes and closes in four hours looks great on a dashboard. It says nothing about whether the fix addressed a root cause or just papered over it until the next release breaks something adjacent. Over a year, this adds to a codebase held together by hundreds of small, disconnected patches, each one technically correct and collectively making the system harder to change.
This is why backlog size is often a better health indicator than SLA compliance. A shrinking backlog means the team is resolving issues faster than new one’s surface, which only happens when fixes are structural rather than cosmetic. A flat or growing backlog, even with perfect SLA numbers, usually means the team is running in place.
Reactive maintenance versus structural maintenance
Most contracts are built around a reactive model: something breaks, a ticket gets filed; someone fixes it. This model works fine for isolated, low-frequency issues. It falls apart when the same categories of bugs keep returning, because nobody on a reactive team has the mandate, or the time, to step back and ask what’s generating them.
Structural maintenance looks different. It treats recurring bug patterns as signals rather than noise. If three tickets in a quarter all trace back to the same brittle integration point, a structural approach flags that integration for a proper refactor instead of a fourth patch. This requires a team that reads the ticket queue as a dataset, not just a to-do list, and that has the authority to recommend working beyond what any single ticket asked for.
The difference shows fastest in legacy systems, where years of accumulated patches have created dependencies nobody fully documented. A reactive fix in one area can quietly break something two modules away, and the team only finds out when the next ticket comes in. Structural maintenance builds in the regression testing and dependency mapping that catches this before it reaches production, rather than after.
What a backlog that never shrinks is telling you
A flat backlog is rarely a resourcing problem, even though that’s the first place most organizations look. Adding more engineers to a reactive process usually just means more tickets get closed at the same shallow depth, which keeps the backlog flat instead of shrinking it. The real signal is usually structural: the maintenance model is optimized for closing tickets, not for reducing the total surface area of things that can break.
This is also where the choice of development partner starts to matter, often well before a maintenance contract is even signed. Applications built by a team offering custom web application development services with root-cause discipline baked into the original build ship with fewer of these recurring defects to begin with, because catching a fragile integration pattern during development costs a fraction of what it costs to keep patching around it in production for the next three years. A backlog that never shrinks is sometimes a maintenance problem. Just as often, it’s evidence that the original build never had anyone asking these questions in the first place.
Choosing a partner that thinks past the ticket queue
The gap between a maintenance vendor that closes tickets and one that actually shrinks the backlog usually comes down to how the engagement is structured from day one. A team offering web application maintenance services worth the contract will ask for access to historical ticket data before quoting a scope, because that history is where the recurring patterns in a web application live. It will propose a triage model that separates true one-off fixes from symptoms of a deeper issue, and it will report both categories separately rather than folding everything into a single resolution-time number.
It also helps to look at how a prospective partner staffs the engagement. Reactive-only teams tend to rotate junior engineers through ticket queues with little continuity, which means nobody develops the system of knowledge needed to spot patterns across releases. A team built for structural maintenance keeps the same engineers on an application long enough to recognize when a new ticket is really an old problem wearing a different symptom.
None of this means every fix needs to become a major refactor. Plenty of tickets really are isolated and deserve a quick, contained fix. The distinction that matters is whether the maintenance process has a mechanism for telling the difference, and whether someone is looking at the pattern across tickets rather than treating each one as unrelated.
What to ask before renewing
A handful of questions during contract renewal can surface whether a maintenance engagement is actually structural or just fast at closing tickets. Ask for the recurrence rate on defects, meaning how many tickets this quarter were repeat issues in a module that was “fixed” in a prior release. Ask whether the team maintains any kind of technical debt log alongside the ticket queue, and whether that log ever drives a proposed piece of work outside the standard SLA. Ask how often the team recommends a fix that goes beyond the literal scope of the ticket that was filed, because a team that never pushes back on scope is a team optimizing purely for closure speed.
The answers tend to be revealing. A vendor with nothing to say about recurrence, no technical debt tracking, and no history of recommending broader fixes is running a pure reactive model, regardless of what the sales deck promised. That model can still be useful for stable, low-change systems where bugs really are isolated events. It becomes expensive for anything under active development, anything with a long history of patches, or anything where the same handful of modules keep generating tickets quarter after quarter.
It’s also worth checking how maintenance work gets prioritized when the backlog competes with new feature requests. In many organizations, maintenance tickets quietly lose priority every time a stakeholder asks for a new feature, which means the backlog grows not because the maintenance team is bad at its job but because it’s never given the room to do more than triage. A contract that protects a fixed percentage of capacity for structural fixes, separate from feature work, tends to produce very different long-term outcomes than one where maintenance is whatever’s left after everything else is scheduled.
Also Read: Basics in Testing: A QA Lead’s No-Nonsense Guide to Software Testing Fundamentals
Getting the backlog moving again
Organizations stuck with a flat backlog rarely need a bigger team. They need a maintenance model that treats the ticket queue as evidence rather than a checklist, one that separates noise from the signal and fixes the signal at its source. That shift changes what maintenance buys an organization: not just uptime and SLA compliance, but a codebase that gets easier to work overtime instead of harder.
The next time a maintenance report lands with perfect SLA numbers and an unchanged backlog, that gap is worth investigating before renewing the contract. The numbers that matter most are often the ones nobody is tracking yet.