
✅ True — Large Language Models (LLMs) are a subset of Foundation Models.
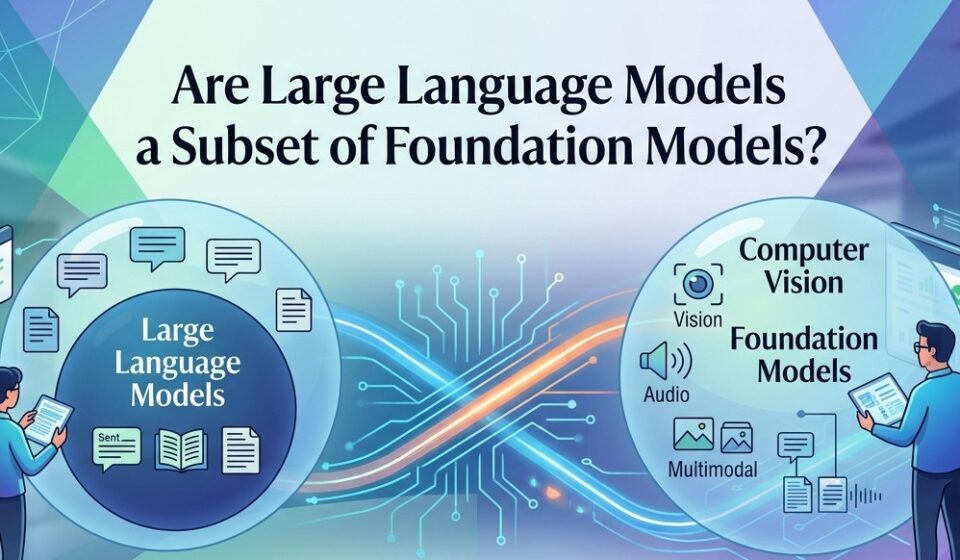
Every LLM is a foundation model, but not every foundation model is an LLM. Foundation Models is the broader category — covering text, image, audio, and video models — and LLMs are the branch of that category that specializes in language.
If you searched this exact statement — “Large Language Models are a subset of Foundation Models” — you’re probably trying to confirm an answer for an exam, an interview, or your own understanding of modern AI terminology. The one-line answer is True. But a one-line answer doesn’t actually teach you why it’s true, and that “why” is what gets tested in follow-up questions, viva rounds, and real-world system-design conversations.
This guide gives you the complete picture: clear definitions, the exact hierarchy these terms sit in, a side-by-side comparison table, real examples of both categories, and answers to every common variation of this question you’re likely to encounter.
On this page
What Is a Foundation Model?
A foundation model is a large-scale AI model trained on broad, diverse data — usually through self-supervised learning — so that it can be adapted, fine-tuned, or prompted for a wide range of downstream tasks it wasn’t explicitly trained for. The term was coined and popularized by researchers at the Stanford Institute for Human-Centered AI (HAI) in an August 2021 paper led by Rishi Bommasani and colleagues, precisely because these models act as a “foundation” that many specialized applications get built on top of.
The defining traits of a foundation model are:
- Broad pre-training on massive, general-purpose datasets rather than a narrow, task-specific one.
- Task-agnostic design — the same base model can be adapted for dozens of unrelated jobs through fine-tuning or prompting.
- Modality flexibility — a foundation model can be built for text, images, audio, video, code, or a combination of these (multimodal).
- Emergent capabilities that weren’t explicitly programmed, arising simply from scale.
Foundation Models is an umbrella term. Under that umbrella sit several specialized families: language models, vision models, speech models, and multimodal models. That’s the key detail people miss.
What Is a Large Language Model?
A Large Language Model (LLM) is a foundation model trained specifically on text data — books, articles, code, conversations, and web content — to understand and generate human-like language. LLMs use transformer-based architectures and typically contain billions to trillions of parameters, which is where the word “large” comes from.
LLMs are built for tasks like:
- Answering questions and holding conversations
- Summarizing and translating text
- Writing and debugging code
- Reasoning through multi-step problems
- Generating essays, emails, and creative writing
Notice that every one of these tasks is language-based. That single-modality focus is exactly what separates an LLM from the broader foundation model category — and it’s the reason the subset relationship holds.
Why LLMs Are a Subset of Foundation Models
Think of it as a set of nested circles, from most general to most specific. Every level below sits entirely inside the level above it:
Artificial Intelligence (AI)
↳ Machine Learning
↳ Deep Learning
↳ Foundation Models (text, vision, audio, video, multimodal)
↳ Large Language Models (text-only foundation models)
Foundation Models is the parent set. It includes every model that fits the “trained broad, adapted for many tasks” definition, regardless of what kind of data it works with. LLMs are one branch inside that set — specifically, the branch that works exclusively with text.
Other branches sitting alongside LLMs, inside the same Foundation Models circle, include:
- Vision foundation models — trained on images (e.g., for classification, detection, generation)
- Vision-language models — trained on paired image-text data (e.g., CLIP)
- Audio/speech foundation models — trained on sound (e.g., for transcription, voice generation)
- Video foundation models — trained to generate or understand video
- Multimodal foundation models — trained across two or more data types at once
Because every LLM satisfies the foundation model definition (broad pre-training, task-agnostic, adaptable) while also adding the extra, narrower constraint of “text-only,” LLMs form a proper subset. This is exactly the kind of parent–child, general–specific relationship set theory calls a subset: everything in the smaller set (LLMs) belongs to the larger set (Foundation Models), but the reverse isn’t true.
Quick logic check: If X is a subset of Y, every member of X must be a member of Y, but Y can contain members that aren’t in X. Every LLM is a foundation model (✓), but Stable Diffusion is a foundation model that is not an LLM (✓ — it proves Y is bigger than X). That’s exactly the relationship here.
LLM vs Foundation Model: Comparison Table
| Attribute | Foundation Model | Large Language Model |
|---|---|---|
| Category level | Parent / umbrella category | Subset / specialized branch |
| Data modality | Text, image, audio, video, code, or any combination | Text only (by definition) |
| Primary goal | General-purpose base for many downstream applications | Understanding and generating human language |
| Typical examples | GPT-4, Stable Diffusion, CLIP, Sora, Whisper | GPT-4, Claude, Gemini, LLaMA, Mistral, BERT |
| Adaptation method | Fine-tuning, prompting, RAG, transfer learning | Same techniques, applied to text tasks |
| Output type | Text, images, audio, video, embeddings — depends on the model | Text (and increasingly structured data, code) |
| Relationship | Contains LLMs as one of its branches | Is always a type of foundation model |
Note: GPT-4 and similar models appear in both columns because a text-focused LLM is, by definition, also a foundation model — it just happens to belong to both categories at once.
Also Read: AI Bola Review 2026: What It Is, How It Works, and Alternatives
Real-World Examples of Each
LLMs (text-only foundation models)
- GPT-4 / GPT-4o (OpenAI)
- Claude (Anthropic)
- Gemini (Google DeepMind)
- LLaMA 3 (Meta)
- Mistral / Mixtral (Mistral AI)
- BERT (Google, encoder-only, earlier generation)
Foundation Models that are NOT LLMs
- Stable Diffusion / DALL-E 3 — text-to-image generation
- CLIP — joint vision-language embeddings, not text generation
- Sora — text-to-video generation
- Whisper — speech-to-text transcription (audio-focused)
- SAM (Segment Anything Model) — image segmentation
This second list is the fastest way to prove the subset relationship to yourself: every one of these is unmistakably a foundation model (broad training, adaptable to many tasks), and none of them is an LLM, because none of them works primarily with language.
More True/False Statements, Answered
These are the most common variations of this question that show up in coursework and quiz banks. Each is answered and explained below.
Statement: “Large Language Models are a subset of Foundation Models.”
Verdict: True.
This is the correct, standard direction of the relationship — LLMs sit inside the broader foundation model category.
Statement: “Foundation Models are a subset of Large Language Models.”
Verdict: False.
This reverses the hierarchy. Foundation Models is the larger, parent category — it cannot be a subset of the smaller category it contains.
Statement: “All Foundation Models are Large Language Models.”
Verdict: False.
Image, audio, and video foundation models exist and are not LLMs, so this over-generalizes.
Statement: “All Large Language Models are Foundation Models.”
Verdict: True.
By definition, an LLM is built through the same broad pre-training and task-agnostic adaptation process that defines a foundation model — just restricted to text.
Statement: “LLMs can only process and generate text.”
Verdict: Mostly false in 2026.
Many models originally described as LLMs (like GPT-4o and Gemini) are now multimodal, accepting images and audio too. Strictly speaking, once a model handles more than text, it’s more accurately called a multimodal foundation model rather than a pure LLM — but the industry still often uses “LLM” loosely to describe these systems.
Common Misconceptions
- “LLM and Foundation Model mean the same thing.” They’re closely related and often used interchangeably in casual conversation, but technically LLM refers to a text-specialized subset, while Foundation Model is the broader, modality-agnostic term.
- “Bigger always means it’s a foundation model.” Size (parameter count) alone doesn’t qualify a model as a foundation model. The defining trait is broad pre-training combined with adaptability across many downstream tasks — not just scale.
- “Foundation models are a new type of neural network.” They’re not a new architecture — most are built on the transformer architecture, same as many LLMs. “Foundation model” describes a training philosophy and use pattern, not a distinct network design.
Why This Distinction Actually Matters
Beyond exams, this distinction has practical weight:
- For engineers: Choosing between an LLM API and a multimodal foundation model API changes your entire architecture — input handling, cost, and latency all differ.
- For businesses: Vendor comparisons and AI governance policies (model cards, risk assessments) increasingly require you to classify a model correctly — “language model” vs. “foundation model” affects which compliance checklist applies.
- For students and researchers: Getting the direction of the subset relationship right is a strong signal of genuine understanding versus memorized buzzwords — it’s a favorite trick question precisely because the reversed statement sounds equally plausible.
Also Read: AI Transformation Is a Governance Problem
Frequently Asked Questions
Is GPT-4 a Large Language Model or a Foundation Model?
Both. GPT-4 is a Large Language Model because its core strength is text, and it’s also a Foundation Model because it was broadly pre-trained and adapted for many tasks. The multimodal version of GPT-4 that accepts images is more precisely described as a multimodal foundation model.
Who coined the term “foundation model”?
Researchers at Stanford’s Center for Research on Foundation Models (part of Stanford HAI) introduced the term in an August 2021 report led by Rishi Bommasani and more than 100 co-authors.
Is a Large Language Model a type of Deep Learning model?
Yes. The full hierarchy, from broadest to narrowest, is: Artificial Intelligence → Machine Learning → Deep Learning → Foundation Models → Large Language Models.
What’s an example of a Foundation Model that isn’t an LLM?
Stable Diffusion and DALL-E (text-to-image), Sora (text-to-video), and Whisper (speech-to-text) are all foundation models that are not LLMs, since none of them specialize in generating language as their primary output.
Do all foundation models use the transformer architecture?
Most do, since transformers scale well and handle long-range dependencies effectively, but the term “foundation model” describes training scale and adaptability — not a mandatory architecture. Some foundation models use diffusion or hybrid architectures instead.
Now that you’ve seen the full definitions, hierarchy, comparison table, and every common variation of this true/false question, you’re equipped not just to answer it correctly, but to explain exactly why — which is what actually gets rewarded in exams, interviews, and technical discussions.
ToniOfTech AI Research Desk
We track terminology, architecture, and product shifts across the large language model and foundation model ecosystem so our explainers stay accurate as the field moves. Have a correction or a follow-up question? Reach out via our contact page.




[…] Also Read: Are Large Language Models a Subset of Foundation Models? (True or False, Explained) […]